Meta releases 'Muse Voice Transcribe,' a real-time transcription AI.
Meta Superintelligence Labs has announced its first real-time speech recognition model, ' Muse Voice Transcribe .' This model marks a significant milestone for Meta's real-time speech models, featuring real-time streaming speech recognition, dialogue recognition for more than 20 speakers, and utterance end detection, and has been ranked number one on the AI evaluation platform Artificial Analysis.
Introducing Muse Voice Transcribe | Meta AI Research
Introducing Muse Voice Transcribe, the first real-time audio perception model from Meta Superintelligence Labs.
pic.twitter.com/x6rfDI5ocB — AI at Meta (@AIatMeta) September 1, 2026
Muse Voice Transcribe delivers real-time streaming ASR, diarization with 20+ speakers, and endpointing. It's multilingual with seamless code-switching and improves…
'Muse Voice Transcribe' is an autoregressive multimodal model in the 'Muse Spark' family of multimodal inference models developed by Meta Superintelligence Labs.
Meta announces native multimodal inference model 'Muse Spark' as part of a 'fundamental overhaul' of its AI business - GIGAZINE
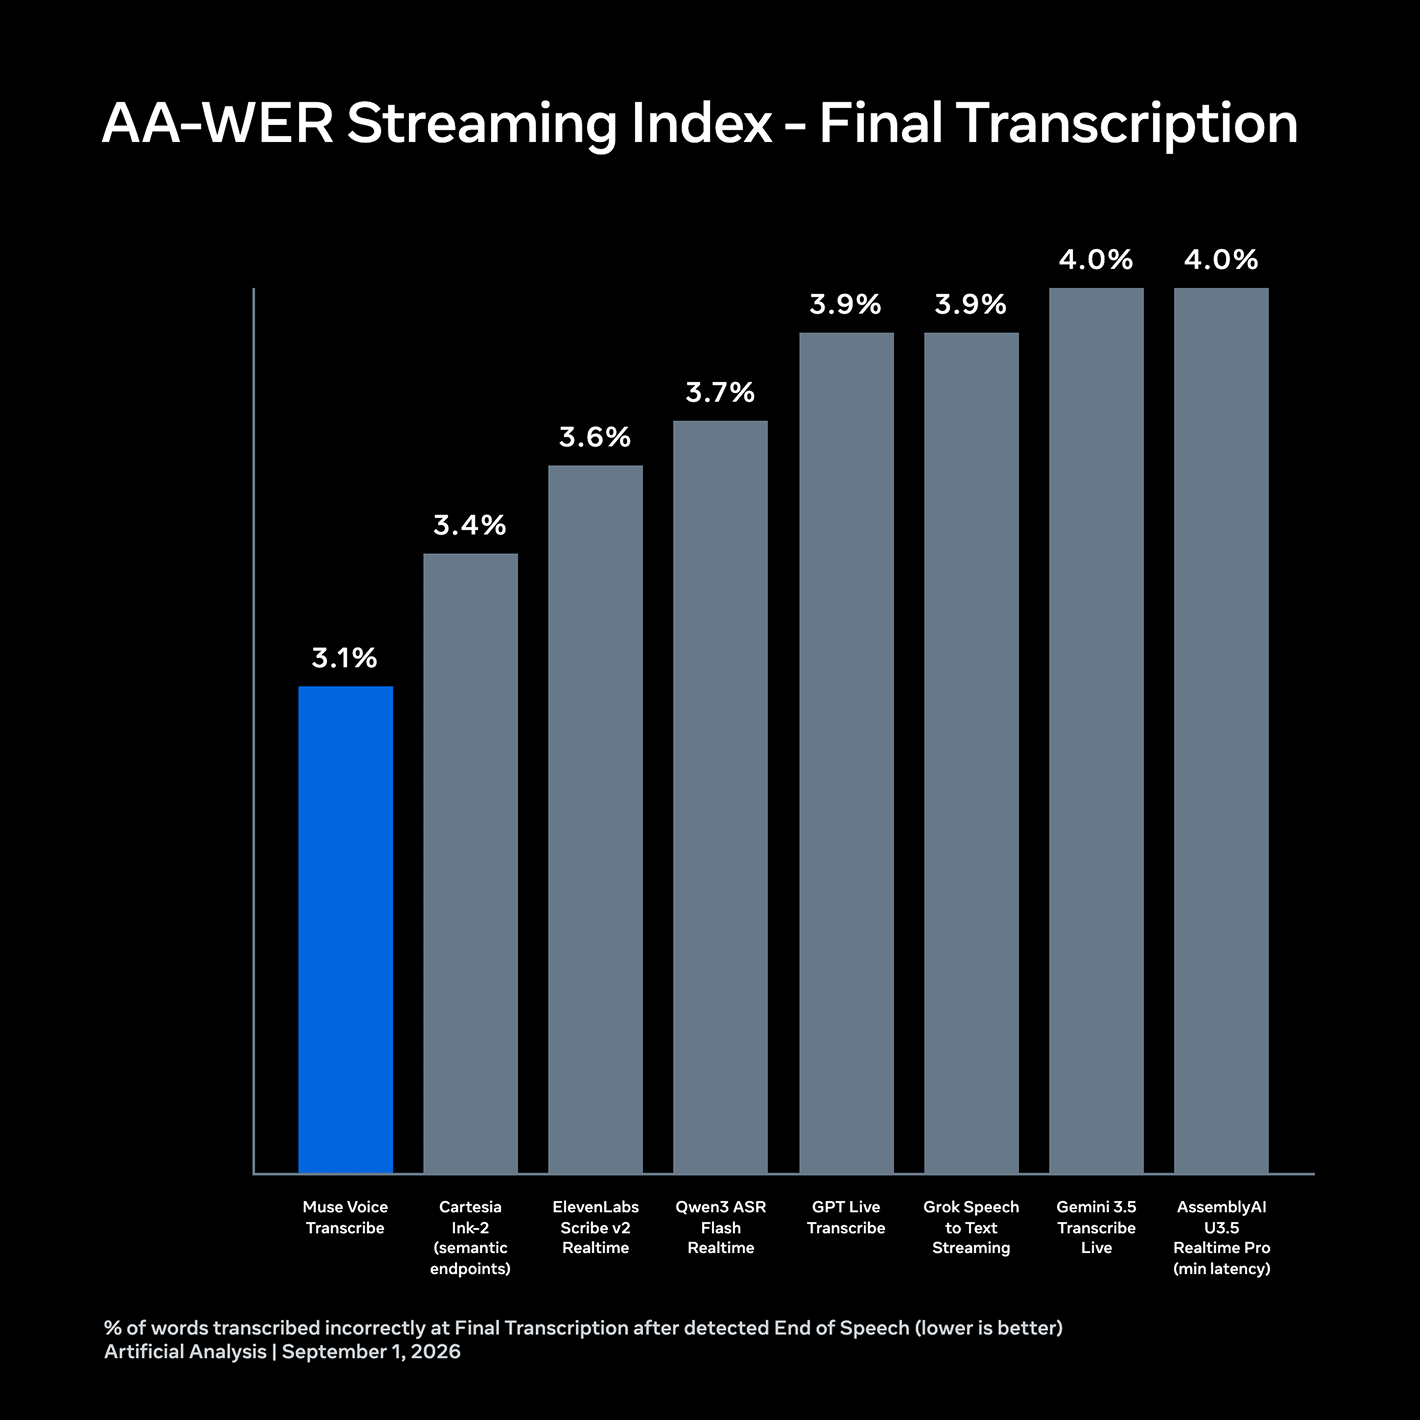
Here's the streaming speech recognition score for 'Muse Voice Transcribe' in Artificial Analytis. It shows the percentage of words that were incorrectly transcribed in the 'final transcription' after detecting the end of speech. A lower percentage indicates higher accuracy, and Muse Voice Transcribe's score is 3.1%.
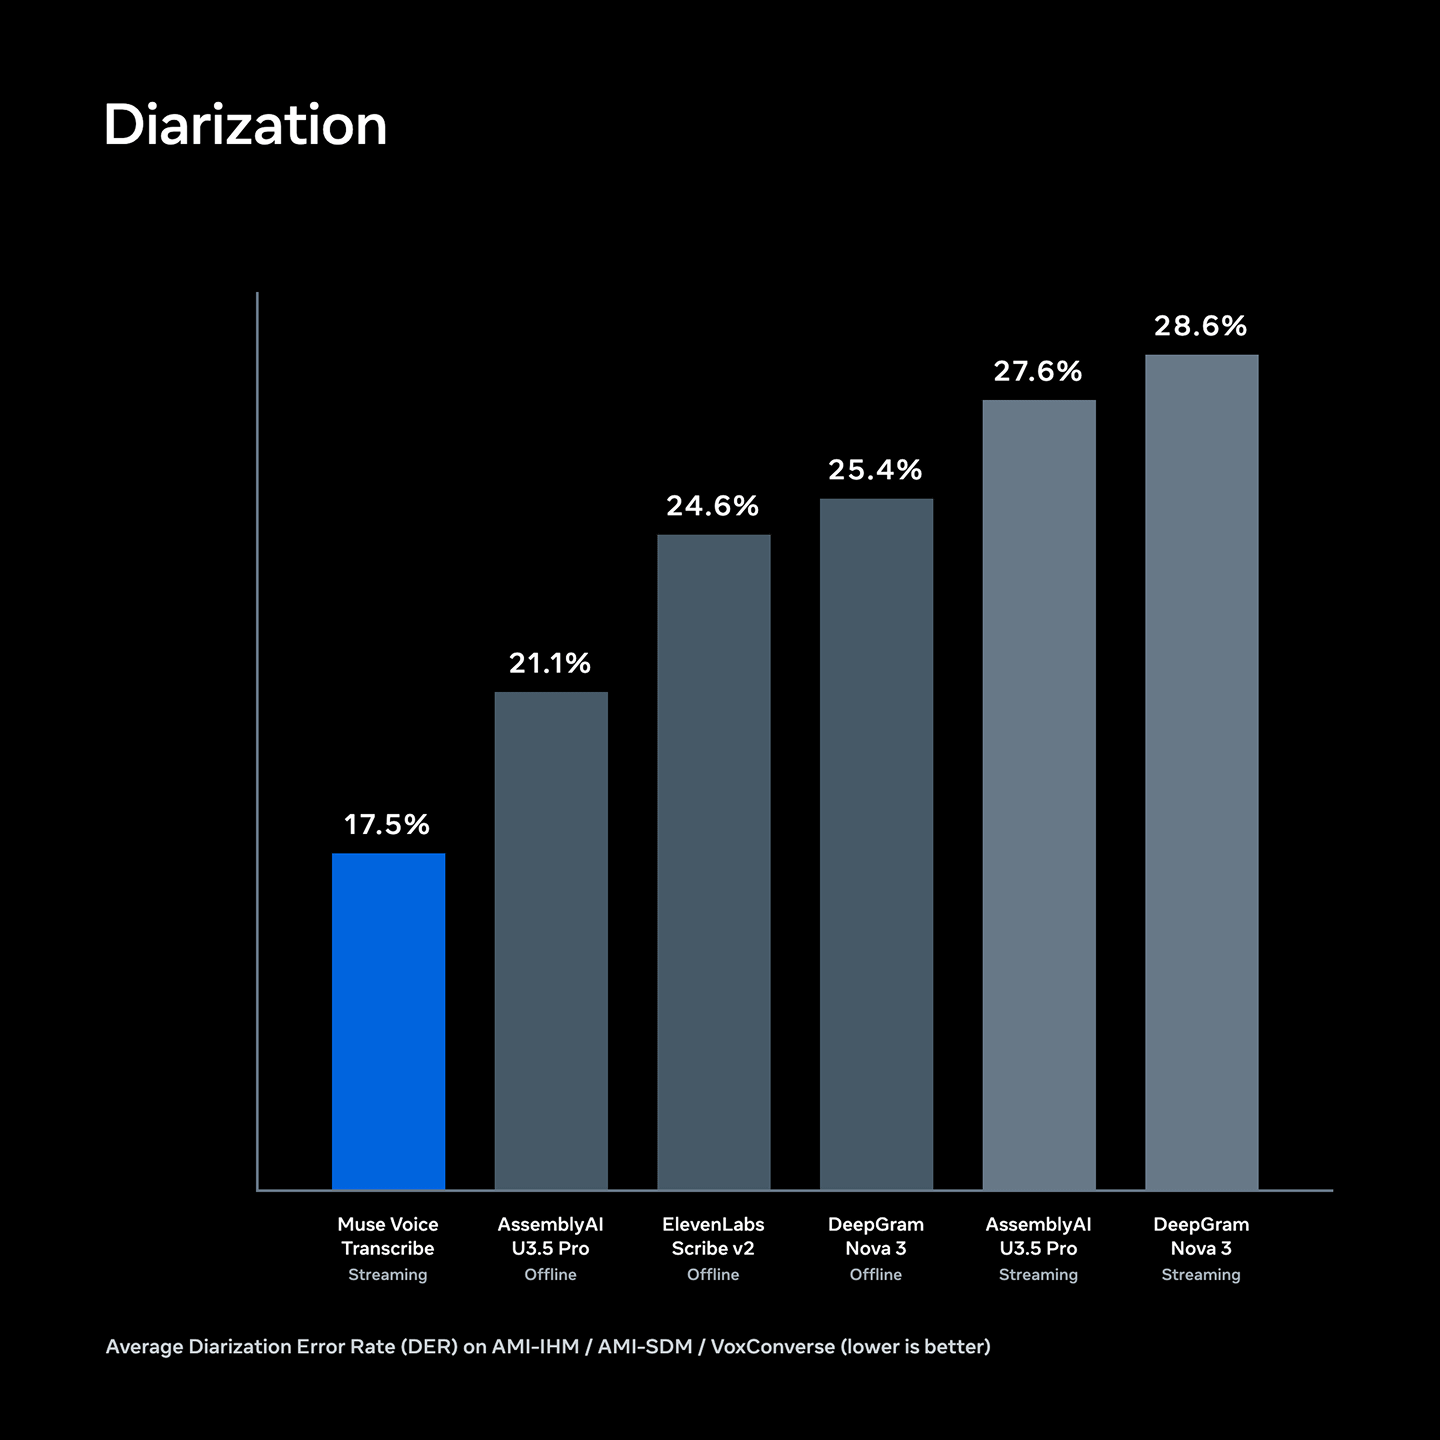
The score indicating the ability to identify speakers also shows a lower misrecognition rate compared to other models.
According to Artificial Analysis, the Muse Voice Transcribe is cheaper than other models, costing '$0.18 per hour (approximately 29 yen)' or '$3 per 1000 minutes (16 hours and 40 minutes) (approximately 480 yen)'.
The training uses over 70 languages, with the following 25 languages being particularly extensively validated.
Arabic
Bengali
Dutch
·English
·French
German
Hebrew
Hindi
Indonesian
Italian
·Japanese
Kannada
·Korean
Malay
・Chinese (Mandarin)
Marathi
Polish
Portuguese
Spanish
Tagalog
Tamil
Telugu
Thai
Turkish
Vietnamese
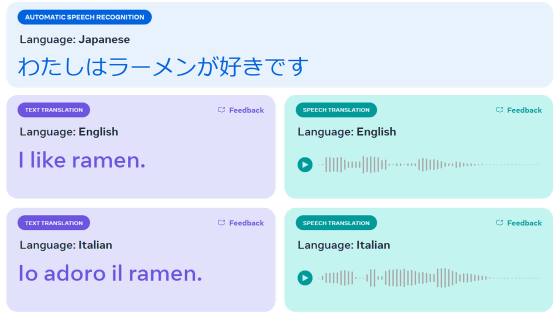
For bilingual speakers, code-switching—the act of switching between words from multiple languages—is commonplace. Muse Voice Transcribe natively supports code-switching both sentence-by-sentence and within-sentence, and improves recognition accuracy by utilizing contextual bias.
Furthermore, it supports audio recordings of over an hour and conversations involving more than 20 people, and requires no post-recording processing such as speaker labeling or level adjustment.
Muse Voice Transcribe will be available from September 2, 2026, via the Meta Model API, Meta AI for Mac, and Muse Code.
Related Posts:

in AI, Posted by logc_nt