Tencent has released its AI model 'Hy4 preview,' which surpasses GPT-5.6 Sol in some tests, and has also released a 1-bit quantized version that is lighter at 213GB.
Tencent, a major Chinese technology company, released its AI model ' Hy4 preview ' on August 28, 2026. It boasts performance comparable to cutting-edge models such as GPT-5.6 Sol and is available free of charge as an open model.
Introducing Hy4 preview | Tencent Hy
🚀 Hy4 preview is here.
— Tencent Hy (@TencentHunyuan) August 28, 2026
770B, 49B active, 1M context.
Built for productivity.
Open source frontier.
Consistent affordable price.
Use it. Tell us what breaks.
More on Hy blog: https://t.co/rbl1IWRk3C
HuggingFace: https://t.co/mE9wevH5XR
Github: https://t.co/pyl9zckpoL pic.twitter.com/4iW6gSuZKr
Hy4 preview is a MoE model with a total of 770 billion parameters and 49 billion active parameters, and a maximum context length of 1 million tokens.
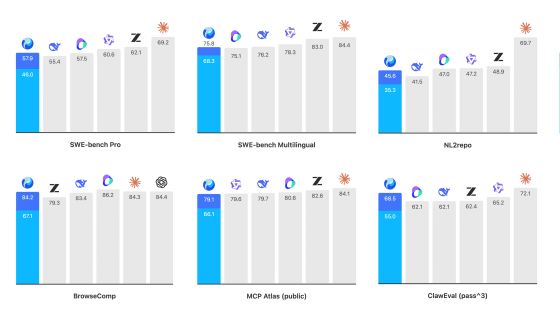
Tencent is promoting Hy4 preview as a 'cutting-edge open model.' Below are the benchmark results for various devices including 'Hy4 preview (dark blue),' 'Hy3 (light blue),' 'Qwen3.8 Max,' 'DeepSeek V4 Pro 0813,' 'GPT-5.6 Sol,' 'GLM-5.3,' 'Kimi K3,' and 'Claude Opus 5.' Hy4 preview outperforms GPT-5.6 Sol in SWE Atlas Refactoring, which measures agent performance.
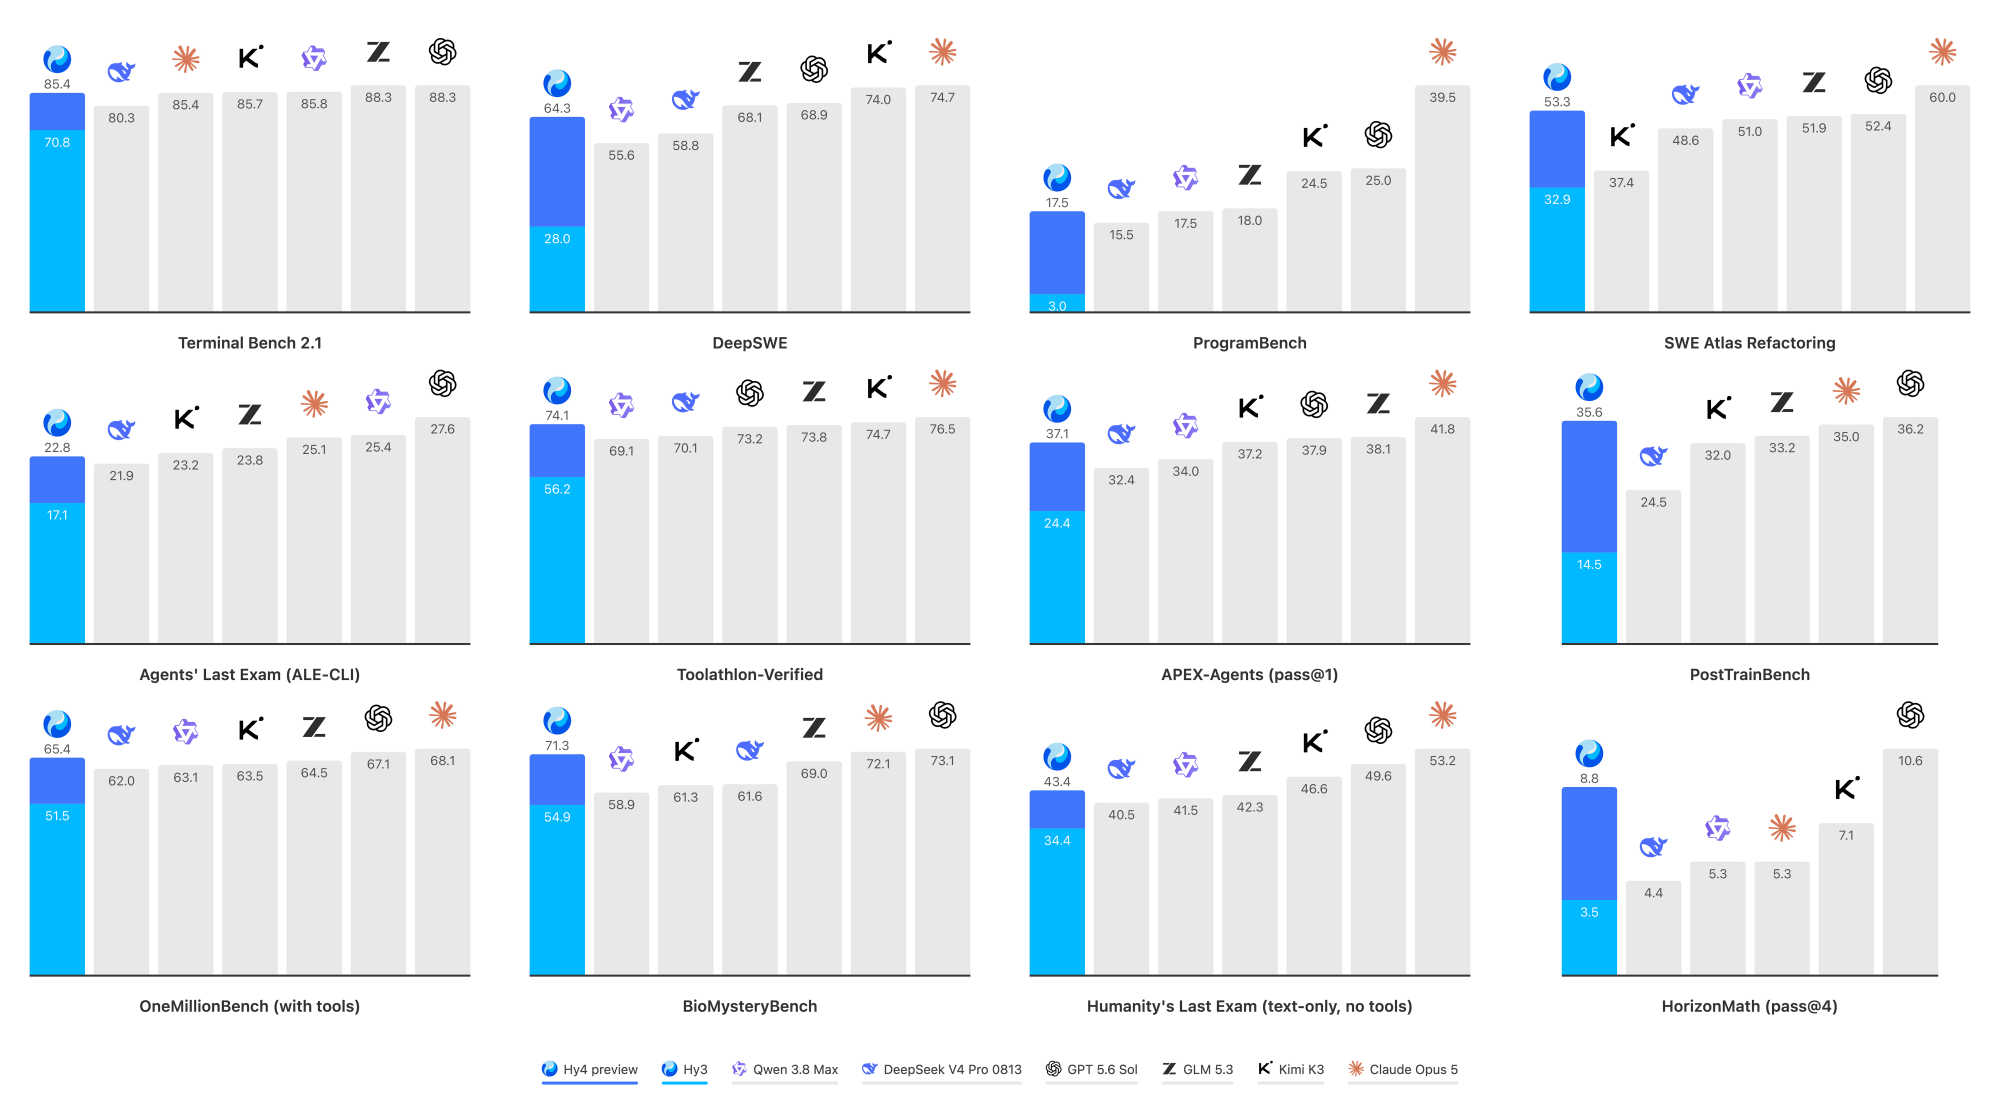
It also surpassed GPT-5.6 Sol in SWE-bench Pro.
Tencent Hy4 Preview leads on SWE-bench Pro. 770B, 49B active, 1M context, and their biggest generational leap measured to date.
pic.twitter.com/ZHGocCJCnU — Cline (@cline) August 28, 2026
It's exciting to see another open weights model compete against the frontier.
Try in Cline with:
1. npm i -g cline
2. /model
3. Select Hy4 preview
Hy4 preview is said to improve the ability to understand, plan, and verify long-term tasks, and is suitable for a wide range of tasks such as document creation and game development.
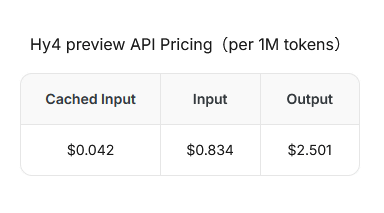
The API fees per million tokens are $0.042 (approximately 6.7 yen) for cached input, $0.834 (approximately 133.4 yen) for normal input, and $2.501 (approximately 400.0 yen) for output.
Hy4 preview is released as an open model and can be downloaded from the following link. It is licensed under the Apache License 2.0. However, running Hy4 preview requires approximately 1.5TB of VRAM.
tencent/Hy4-preview · Hugging Face
https://huggingface.co/tencent/Hy4-preview
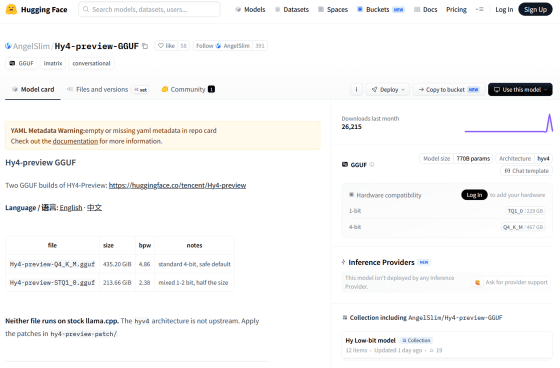
Tencent has also released quantized versions of Hy4-preview, which can run on 435 GiB of VRAM for the Q4_K_M version and 214 GiB for the STQ1_0 version.
We compressed Hy4-preview from 1.5TB to ~200GiB GGUF and it still works well!
— Tencent Hy (@TencentHunyuan) August 29, 2026
Meet MIX-STQ1_0.The trick isn't just going low, it's deciding where: calibration data picks each layer's bit-width, some down to 1.31-bit STQ1_0, some up to 2.06-bit IQ2_XXS. Same budget, lower… https://t.co/HItkQ1TSxA pic.twitter.com/xK8d3BH5br
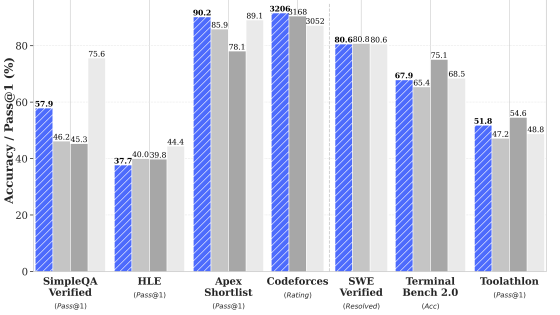
The STQ1_0 version employs a method of 'selecting the target to quantize and using 1.31-bit STQ1_0 and 2.06-bit IQ2_XXS interchangeably,' which reportedly succeeds in minimizing performance degradation. The graph below compares the benchmark scores of the BF16 version (the original model without quantization) and the STQ1_0 version, showing that the performance difference is small relative to the difference in size.
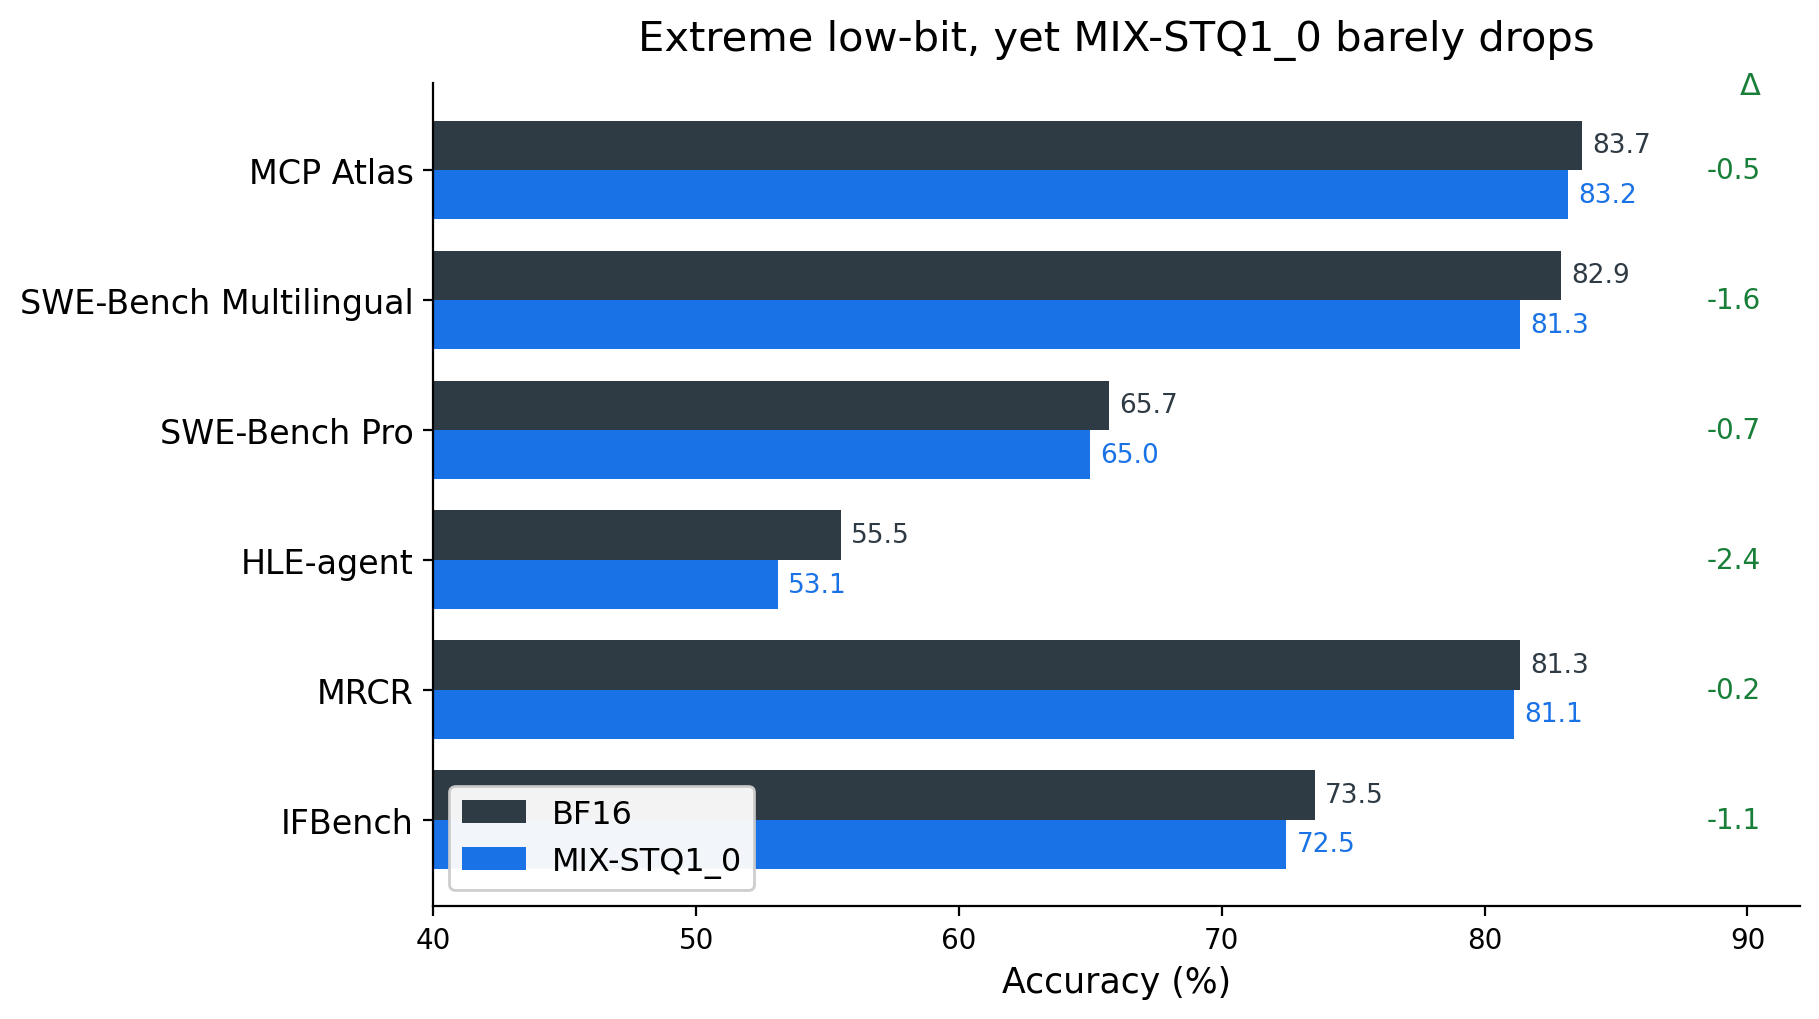
The quantized version of Hy4-preview can be downloaded from the following link.
AngelSlim/Hy4-preview-GGUF · Hugging Face
https://huggingface.co/AngelSlim/Hy4-preview-GGUF
Related Posts:
in AI, Posted by log1o_hf