We had Grok 4.5, GPT-5.5, Claude Opus 4.8, and Fable 5 build the same application, and measured latency and cost. Which AI won?
Regarding
We made Grok 4.5, GPT-5.5, and Claude build the same apps · TryAI
https://www.tryai.dev/blog/grok-4.5-vs-gpt-5.5-vs-claude-build-off
·table of contents
◆1: Solving a 3D Rubik's Cube by Shuffling
◆2: Particle Gravity Sandbox
◆3: Block Breaker Game
◆Bonus: Image generation
◆ Cost
◆Overall evaluation
TyrAI gave each AI model three prompts: 'Create a single, self-contained HTML file for an interactive app without using any libraries or network calls.' Each prompt was given only once, and no further instructions or adjustments were made afterward. All results were then loaded into a real browser, interacted with, and the results recorded.
◆1: Solving a 3D Rubik's Cube by Shuffling
The first prompt is: 'Assemble a colorful, three-dimensional Rubik's Cube with 'Scramble' and 'Solve' buttons. The cube's rotation must be visually animated.'
Build a colorful, 3D-looking Rubik's Cube with 'Scramble' and 'Solve' buttons. The cube must visibly animate its rotations.
This is whatan app developed with Grok 4.5 looks like. With Grok 4.5, the title and buttons were rendered, but the cube wasn't rendered at all, and this app was finally output on the second attempt.
This is an app developed by GPT-5.5. For some reason, it's a flat surface instead of a cube.
Apps developed with Opus 4.8 are outputting exactly what is required.
The Fable 5 app has also been developed exactly as requested. According to TryAI, Opus 4.8 and Fable 5 were able to output a 3D cube that automatically scrambles and solves while rotating with animation in a single click.
◆2: Particle Gravity Sandbox
The second prompt asks you to develop a sandbox app that depicts countless particles and allows you to observe their movement by generating gravity wherever you click.
An interactive particle gravity sandbox on a canvas: hundreds of particles with trails, clicking adds a heavy attractor. Make it mesmerizing.
This is the sandbox output by Grok 4.5. TryAI praised it, saying, 'It created a clean, orbital sandbox with orderly attractors and colorful, streaky particles.'
This is what the sandbox developed by GPT-5.5 looks like. TryAI commented, 'The most captivating sandbox, with its dazzling neon trails and dense, swirling color trajectories.' Since all the AIs produced working sandboxes this time, TryAI chose GPT-5.5's sandbox as number one based on its preference and overall feel.
Opus 4.8 sandbox . TryAI rated it as 'generating the most bustling and mesh-like particle field, with excellent physics, but somewhat lacking in visual appeal.'
Fable 5's sandbox is a work that focuses on soft, glowing spheres rather than particles.
◆3: Block Breaker Game
The third prompt asks you to create a brick-breaking game where you use the mouse to control a paddle and destroy colorful blocks with a ball.
A playable Breakout / brick-breaker on a canvas: paddle follows the mouse, ball breaks colorful bricks, with score and lives.
The following is a work created with Grok 4.5. It faithfully reproduces a neon-colored arcade-style design.
The design of the GPT-5.5 has also been reproduced, and it is designed to allow you to earn points even while you are hitting the ball back.
Works created with Opus 4.8 are also perfectly usable.
Here's what the entries for Fable 5 look like. TryAI has ruled that 'all four are at a usable level. There are all winners.'
◆Bonus: Image generation
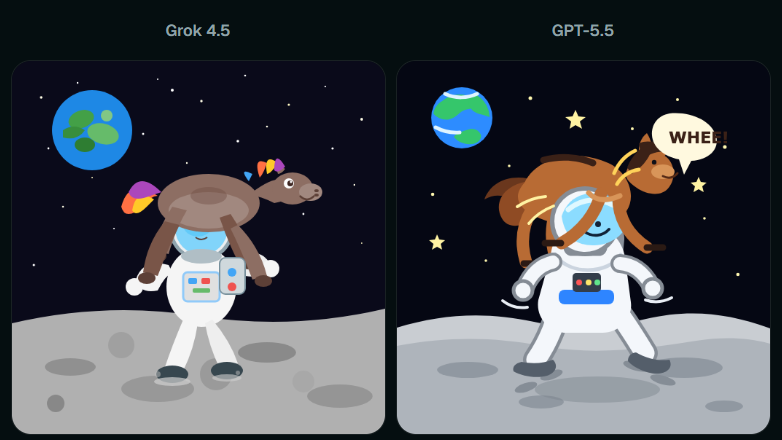
The four models cannot generate raster images such as JPEG or PNG, but they can generate SVG images, which are vector-based images that represent images using mathematical formulas. TryAI gave each model the following prompt and caused it to output an image in SVG format of 'an astronaut walking on the moon with a horse on his back'.
a horse riding piggyback on an astronaut walking on the moon. Role reversal, two figures, one file.
The results are as follows. The best is Fable 5, which draws a cartoonish illustration of a horse wearing a cowboy hat shouting 'Giddy-up, human!' while a hunched-over astronaut is panting heavily. GPT-5.5 also draws an image with dialogue, but the horse's design is somewhat distorted. Grok 4.5's output is colorful and clearly depicts a scene, fulfilling the prompt's intent well. Opus 4.8 also draws 'a horse riding an astronaut,' but the SVG image contains duplicate attributes, making it problematic to render.

◆ Cost
'A visually appealing demo and the actual cost of running each model are two different things,' says TryAI. The table below shows the results of measuring each model in their own test environment, using the same provider routing as used in the app. In the tests, three types of fixed prompts were prepared, including coding, inference, and summarization, and each was run three times. Output was limited to a maximum of 400 tokens. Throughput was measured by dividing the number of output tokens by the total processing time, using the same method for all providers.
| Model | Median latency | Initial token | throughput | Cost per reply | success rate |
|---|---|---|---|---|---|
| Grok 4.5 | 2.8 seconds | 0.44 seconds | 110 tokens per second | 0.002 cents | 100% |
| GPT-5.5 | 2.0 seconds | 1.26 seconds | 53 tokens per second | 0.004 cents | 100% |
| Claude Opus 4.8 | 2.6 seconds | 1.16 seconds | 47 tokens per second | 0.004 cents | 100% |
| Claude Fable 5 | 6.3 seconds | 3.47 seconds | 28 tokens per second | 0.009 cents | 100% |
Grok 4.5 demonstrated its strength in this cost comparison, with a time to the first token being issued in less than 0.5 seconds and an output rate of approximately 110 tokens per second. Its speed was about twice that of the other models, and it also had the lowest cost per response. TryAI states that this aligns with SpaceX AI's marketing slogan of 'intelligence per unit of time and cost.'
Also, while the median processing time appears similar across all methods, this is because Grok 4.5 responses tended to be longer. There was also considerable variation, with the highest number of tokens per response and over 9 seconds in 5% of the responses.
TryAI states, 'GPT-5.5 is the most efficient for short responses, while Claude Opus 4.8 strikes a good balance between speed and cost. On the other hand, Claude Fable 5 is the slowest and most costly. This is the price you pay for using the most intelligent model.'
◆Overall evaluation
TryAI positions Grok 4.5 as 'the best model in terms of speed and cost.' It delivered high-quality results in particle gravity sandbox and brick breaker games, with streaming speeds approximately twice as fast as other models and the lowest execution costs. On the other hand, a weakness was that it failed on the first attempt in the most difficult task, 3D Rubik's Cube, and had to be corrected on retries.
Opus 4.8 and Fable 5 are highly regarded as reliable models that correctly generated 3D cubes on the first try, although Fable 5 in particular is considered burdensome in terms of speed and price. GPT-5.5 excels in fast, short response times and a visually appealing gravity simulator, but it failed with 3D cubes. Overall, TryAI argues that Grok 4.5, despite being newly released, competes on par with the top-tier models and clearly wins in terms of speed and cost.
Related Posts: